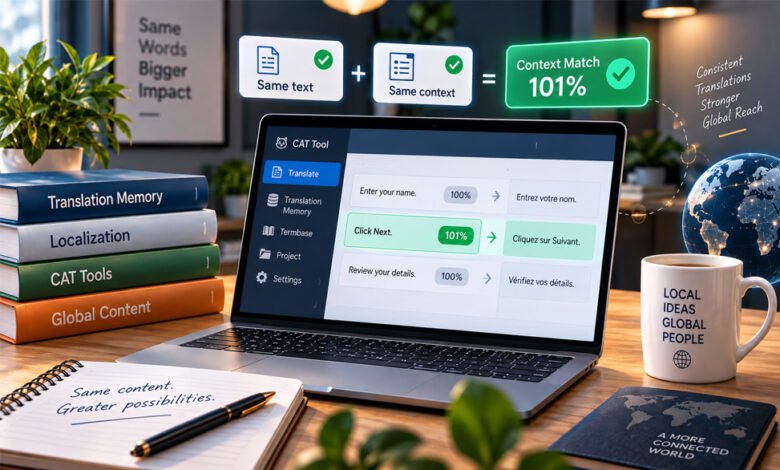

A context match is a type of match used in computer-assisted translation (CAT) tools. It helps translators reuse an old translation when both the source text and its context match previously translated content.
Context matches are closely connected with Translation Memory (TM). They can save time, improve consistency, and reduce repeated translation work.
In this guide, you will learn what a context match is, how it works, how it differs from 100% and fuzzy matches, and why context is important in professional translation.
What Is a Context Match?
A context match happens when a CAT tool finds the same source segment in its Translation Memory and also confirms that the required context matches.
A Translation Memory stores text that has already been translated. For example, it may store an English sentence together with its approved German, French, Spanish, or other translation.
A normal exact match tells the translator that the same source text was translated before. A context match gives extra information. It shows that the text is also being used in the same or matching setting.
Many translation workflows describe this as a 101% match. The number does not mean that the translation is 101% accurate. It is simply a way to separate a contextual exact match from a normal 100% match.
The exact rules are not the same in every CAT tool. A system may check the segment before the current one, nearby segments, document structure, IDs, or other stored information.
This extra check is useful because the same words can have different meanings in different places.
A Simple Context Match Example
Imagine that a Translation Memory contains these three lines:
Enter your name.
Click Next.
Review your details.
Later, another file contains the same three lines in the same order.
The CAT tool already knows that “Click Next” has been translated before. It can also see that the surrounding text matches. This gives the tool more evidence that the old translation is suitable for the new file.
Short words make the value of context even clearer. Take the word “Close.” It may be a button telling someone to close a window. In another sentence, “close” may describe something that is nearby.
The word can be identical while its meaning is different. Context helps the translator understand which meaning is intended.
How Context Matching Works
Context matching starts with a Translation Memory. A TM stores pairs of source and translated text. Each stored pair is usually called a segment.
A segment can be a full sentence, but it can also be a heading, button, label, menu item, or other small piece of text.
When a new file is opened in a CAT tool, the software compares its source segments with entries stored in the Translation Memory.
If it finds similar wording, it may return a fuzzy match. If it finds identical source text, it can return an exact match. To produce a context match, the tool also checks the contextual information required by that system.
For example, a tool may look at the segment that came before the current text. Some workflows can also use document structure, segment position, IDs, or context keys.
Suppose a stored segment says:
Save changes?
The same words might appear in several parts of an application. One could relate to profile settings, while another could appear when editing payment information.
Matching the words alone shows that an old translation exists. Matching useful context provides more evidence that the translation came from the same type of situation.
The exact method depends on the CAT tool and file format. This is why context match should be understood as a general concept rather than one fixed rule used by every translation platform.
Why Context Matters in Translation
Language depends on context. One word or sentence can have different meanings depending on where and how it is used.
For example, consider the word “Home.”
On a website, Home normally refers to the main page. In another piece of content, it may refer to a person’s house. On a device, it could refer to the Home screen.
The source word is still the same. However, another language may need different translations for these meanings.
This problem is common with short text such as buttons, menu items, alerts, headings, and field labels. A long sentence often gives the translator more information about its meaning. A one-word button gives very little information on its own.
Context can help fill this gap.
Suppose “Continue” appears between:
Choose a payment method.
and
Confirm your order.
The surrounding text makes it clear that Continue is part of a checkout process. If the same text and context existed in an earlier approved translation, the CAT tool has a stronger reason to suggest that translation again.
Context is also important because languages work differently. Grammar, gender, formality, case, and other language rules may depend on information outside one small segment.
A context match can reduce uncertainty, but it does not remove the need for human understanding.
Context Match vs. 100% Match
A 100% match normally means that the current source segment is identical to a source segment stored in the Translation Memory.
A context match goes further. Along with finding the same source text, the CAT tool confirms the contextual information required by its matching system.
The basic difference is:
100% match = exact source text
Context match = exact source text + matching context
For example, imagine the phrase “Check the balance.”
In financial content, “balance” may mean the amount of money in an account. In technical content, balance could have a different meaning.
If a Translation Memory contains the exact phrase, a normal 100% match may return the stored translation. But the words alone do not prove that the old translation came from the same situation.
Contextual information can give the translator more confidence that it did.
This does not mean every 100% match is unsafe. Many exact matches are perfectly suitable. It simply means a context match provides an extra check.
A translator may still review either type of match when the content is important or when the Translation Memory contains older material.
Context Match vs. Fuzzy Match
A fuzzy match is different because the source text itself is not identical.
It means the CAT tool found a Translation Memory entry that is similar to the current segment.
For example, the TM may contain:
Your order will arrive in 3 days.
The new sentence might say:
Your order will arrive in 5 days.
Most of the sentence is the same, but the number has changed. The old translation can still be useful, but the translator needs to update it.
Other changes that can produce fuzzy matches include a different product name, an added word, removed text, or changed punctuation.
The percentage used for fuzzy matches depends on the CAT tool and project settings. There is no single percentage range that applies to every translation workflow.
In simple terms, the main match types can be understood like this:
| Match Type | Meaning |
|---|---|
| Fuzzy match | Source text is similar but not identical |
| 100% match | Source text matches exactly |
| Context match | Source text matches exactly and the required context also matches |
Fuzzy matches usually need more checking and editing because something in the source has changed. A context match generally gives stronger evidence that an existing translation can be reused.
Structural Context, IDs, and Metadata
Context does not always mean the sentence before or after a segment.
Modern localization files can contain extra information that helps a CAT tool understand where text belongs. This is often called structural context or metadata.
For example, a tool may know that a segment is used as a heading, table cell, menu item, paragraph, button, or form field.
This matters because the same words may need different treatment in different places. A short phrase used as a menu label may need a compact translation. The same phrase inside a full paragraph may be translated differently.
Software and structured content can also contain unique IDs or context keys. These can help identify the purpose or location of a string.
For example, two buttons may both contain the word “Save.” Their IDs may show that one belongs to account settings while another belongs to a document editor.
This type of information can be especially useful with:
- software localization files
- XML content
- CMS content
- apps and user interfaces
- structured product information
Stable structure and IDs can improve translation reuse. If IDs, segment order, or file structure change between versions, useful contextual information may be lost.
101%, ICE, 102%, and Perfect Matches
CAT tools do not all use the same names or rules for their strongest Translation Memory matches.
A 101% match is commonly used to describe an exact source match that also meets additional context conditions. The extra one percent is a label. It does not measure translation quality as being above perfect.
The term ICE, meaning In-Context Exact, is also used in translation technology for exact matches supported by contextual information.
Some CAT tools provide other high-confidence match types based on additional information. These can involve document structure, IDs, context on more than one side of a segment, or comparison with an earlier bilingual document.
PerfectMatch is another term found in CAT-tool workflows. It can involve comparing new content with an earlier translated bilingual file to identify unchanged content more precisely.
Terms such as 101%, ICE, 102%, XLT, and PerfectMatch should not automatically be treated as identical. Their exact meaning depends on the software being used.
Tools such as Trados Studio, memoQ, and Phrase/Memsource have their own ways of storing and using context. Because of these differences, translators should check the documentation and project settings for their specific CAT tool rather than relying only on the percentage shown beside a segment.
Benefits of Context Matching
A context match can make translation work faster and more consistent. It helps translators reuse text that has already been translated in the same or a matching setting.
One of the main benefits is saving time. Translators do not need to translate the same content again when a suitable translation already exists in the Translation Memory.
It also supports consistency. Buttons, product terms, instructions, warnings, and other repeated text can stay the same across different files and updates.
Context matching can also reduce editing work. When both the source text and its context match, there is more evidence that the stored translation fits the new segment.
Another benefit is better use of a translator’s time. Instead of spending too much time on repeated content, translators can focus on new text, fuzzy matches, and difficult sentences.
For localization teams, this can also make project planning easier. They can see how much content is new and how much may be reused.
Where Context Matches Are Most Useful
Context matching is useful when the same or similar content appears many times.
Software localization is a common example. Apps and programs often reuse buttons, menus, error messages, settings, and other interface text.
It is also useful for websites and CMS content. A website may keep the same menus, forms, notices, and page structure when new content is added.
Technical manuals can contain repeated instructions and safety information. When a new version of a manual is created, much of the older translation may still be useful.
Online stores can also have repeated text in product pages, checkout pages, shipping information, and return instructions.
Context matching can also help with legal, financial, and other structured documents that contain standard or repeated language. However, important content may still need human review even when a strong match is available.
Context Matches and Translation Pricing
Translation Memory matches can affect the cost of a translation project.
Some translation companies use weighted pricing. This means different types of text may be charged at different rates.
New text normally requires the most work because it must be translated from the beginning. A fuzzy match may receive a discount because an older translation gives the translator a useful starting point.
A 100% match may receive a larger discount because the source text is identical. A context match may receive an even larger discount because the source and required context both match.
However, there is no single pricing rule for context matches.
One agency may charge a small review fee for these segments. Another may include them at a very low rate. Some projects may still require every segment to be checked carefully.
Pricing can depend on the language pair, type of content, Translation Memory quality, project requirements, and level of human review.
For this reason, a 101% match should not automatically be treated as free translation work.
Limitations and Risks
A context match is useful, but it is not a guarantee that a translation is correct.
The CAT tool is reusing information stored in the Translation Memory. If that information has a problem, the problem can also be reused.
For example, an old translation may contain a mistake. It may also use a product name or technical term that the company no longer uses.
Brand language can change as well. A translation that was approved several years ago may not follow the current style guide.
Changes to the source files can create other problems. IDs may be replaced, document structure may change, or file conversion may remove useful metadata. A valid old translation may then receive a lower match because the tool can no longer confirm its original context.
The opposite problem is also important. Even when the CAT tool finds matching context, the wider meaning may have changed.
Some languages depend heavily on gender, case, formality, number, or information found in another sentence. The context checked by the software may not always contain everything the translator needs.
Automatically locking every strong match can therefore create problems. If an old translation is wrong, translators need a way to correct it.
When Human Review Is Still Important
CAT tools help translators work more efficiently, but they do not replace human judgment.
A translator may need to review a context match when terminology, product information, writing style, or translation rules have changed.
Review is especially important when a mistake could have serious results. This can include legal text, health information, safety warnings, payment instructions, financial information, and important public-facing content.
The quality of the Translation Memory also matters. A well-maintained TM with approved translations is more useful than one filled with old or conflicting entries.
Human review can also catch problems that a match percentage cannot. The words may match perfectly while the wider purpose of the content has changed.
A high match score should therefore be treated as useful evidence, not automatic proof that no review is needed.
Best Practices for Better Context Matches
Good context matching starts with good source content and a clean Translation Memory.
Keep approved translations in the TM whenever possible. Incorrect, outdated, or poor translations should be corrected or removed so they are not suggested again.
Duplicate entries also need attention. If several TM entries contain different translations for the same source text, translators may receive conflicting suggestions.
Keeping document structure stable can also help. When recurring manuals, websites, or software files use consistent templates, the CAT tool has a better chance of recognizing the same context.
Useful IDs and metadata should also be kept when possible. They can help the software understand where a segment belongs.
Source writers can help too. If the same idea means the same thing, using consistent wording can improve Translation Memory reuse.
Teams should also decide how different match types will be handled. For example, they can set rules for which segments are pre-translated, reviewed, or locked.
High-risk content should still receive suitable human review even when the system reports a strong context match.
Use a Termbase With Translation Memory
A Translation Memory and a termbase are related, but they do different jobs.
A Translation Memory stores larger translated segments, such as sentences, headings, and interface strings.
A termbase focuses on important terms. These can include product names, technical words, approved company terms, and their preferred translations.
For example, a company may require one specific translation for a product feature. Adding that term to the termbase helps translators use it consistently.
Using a clean TM together with a well-maintained termbase can improve consistency across large localization projects.
Context Matching and AI
Traditional context matching mainly depends on stored Translation Memory data and defined matching rules.
The software checks whether the source text and required contextual information meet its matching conditions. This approach does not necessarily require AI to understand the meaning of the sentence.
AI and natural language processing can support a different idea called semantic matching. Instead of looking only for identical words, a semantic system can try to identify text with a similar meaning.
For example, two surrounding sentences may express almost the same idea while using different words. Traditional exact context rules may not treat them as identical. A semantic system could potentially recognize the similarity.
This should not be confused with a standard 101% context match. AI-based semantic matching and traditional Translation Memory matching are different approaches, even though modern translation systems may use several technologies together.
Bottom Line
A context match helps a CAT tool reuse an existing translation with more confidence. The source text matches an entry in the Translation Memory, and the required context also matches.
This can save time, improve consistency, reduce repeated work, and sometimes lower translation costs. It is especially useful for software, websites, manuals, and other content that is updated regularly.
However, the match is only as reliable as the Translation Memory and context behind it. Old errors, changed terminology, weak metadata, or wider language context can still create problems.
A good workflow combines context matching with a clean Translation Memory, clear terminology, stable source files, and human review when it is needed.
Frequently Asked Questions
What is a context match in translation?
A context match means the text and its surrounding context match an older translation stored in Translation Memory.
What does a 101% match mean?
A 101% match means the text matches exactly and its context also matches. It does not mean 101% accuracy.
What is the difference between a 100% match and a context match?
A 100% match checks the exact text. A context match checks both the exact text and its context.
Is a context match the same as a fuzzy match?
No. A fuzzy match is similar but not exact. A context match has exact text plus matching context.
Does every CAT tool use 101% context matches?
No. Different CAT tools may use different names, scores, and rules for context matches.
Can a context match contain a translation error?
Yes. If the saved translation has an old mistake, the CAT tool may suggest the same mistake again.
Do translators need to review context matches?
Sometimes. Important or sensitive content should still be checked, even when the context matches.
How can you get more context matches?
Keep your Translation Memory clean and use consistent text, file structures, IDs, and terms.
What Is Nerwey? Meaning, Uses, and Everything You Need to Know
Assimilasjon Explained: Culture, Language, Biology, and Examples